SPECTRA7 SETS SIGHTS ON 56GBPS PAM4 SERVER

AI Server Chassis Features

AI Server Chassis Features

Our AI server chassis provides a versatile and robust foundation for building customized AI computing solutions. Crafted with high-quality materials and precision engineering, this chassis offers flexibility, scalability, and reliability for housing and protecting your AI server. As an NVIDIA partner, Chenbro is dedicated to promoting the adoption and expansion of the MGX architecture by offering versatile server chassis solutions. Modern AI models are data-hungry, computation-heavy beasts that need specialized hardware just to function, let alone perform at their best. That's the job of an AI server—a custom-built system that keeps AI applications fast, scalable, and efficient. These specialized enclosures are designed to support high-performance hardware like GPUs and TPUs, enabling businesses to handle complex AI workloads such as machine learning, deep learning, and generative AI. Artificial Intelligence (AI) is appearing in many new contexts, placing a spectrum of new demands on enterprise computing—whether in the core data center, branch, remote, and industrial sites, or at the network edge: ● Companies are integrating AI features, such as recommendation engines, into.

Read More
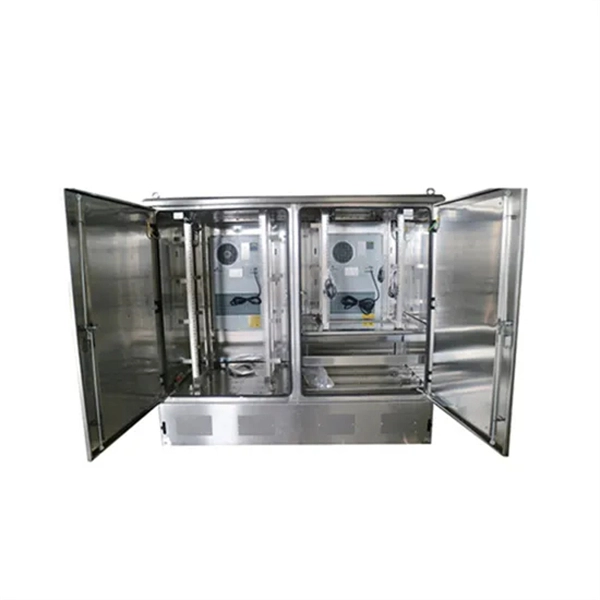
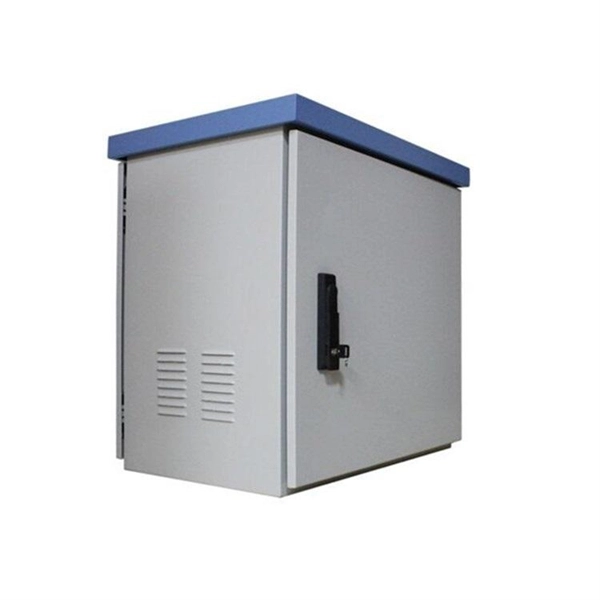
Can temperature-controlled server racks be used outdoors

Can temperature-controlled server racks be used outdoors

An outdoor server rack is a weather-resistant, lockable enclosure designed to house 19-inch IT equipment—servers, switches, routers, power supplies, and environmental controllers—in exposed environments: utility poles, telecom cabinets, parking lots, construction sites, agricultural sensors, or. Premium HVAC outdoor telecom enclosures with NEMA 4/4X ratings for extreme environments. Our temperature-controlled electrical cabinets feature weatherproof, waterproof designs for 19" server racks, fiber distribution & cell tower equipment. Servers inside a data centre rack generate intense heat as they process growing volumes of data, and if that heat remains unmanaged, it can lead to system slowdowns, unplanned shutdowns, or lasting equipment damage.

Read More
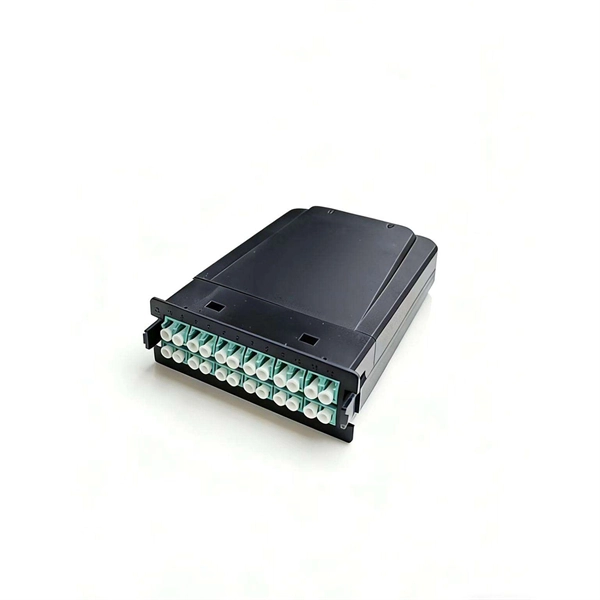
Fiber optic patch panels are installed in the server rack

Fiber optic patch panels are installed in the server rack

The Fiber Optic Patch Panels (ODFs) are connector panels installed into 19" or 21" rack cabinets in data centers and server rooms. It acts as a hub for organizing splices and patch cords, streamlining fiber management and preserving signal integrity. AFL's portfolio includes modular and scalable solutions like the Denali High-Density Platform, LS Series, UltraSlim, U Series, and.

Read More
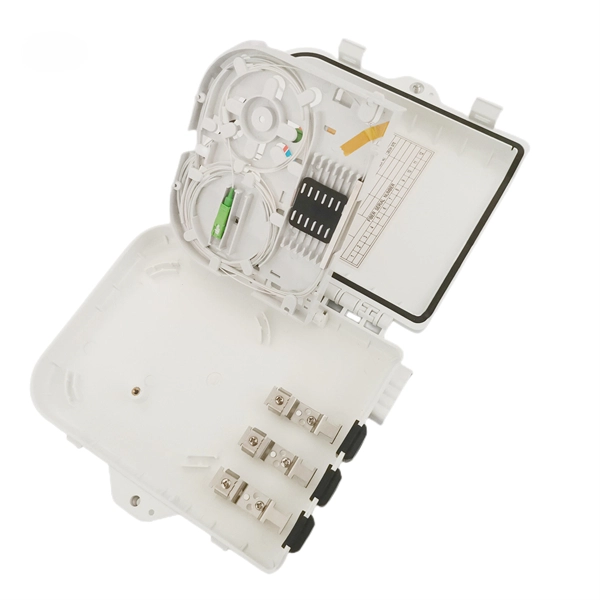
Fiber optic patch panel behind the server rack

Fiber optic patch panel behind the server rack

Rack-mount fiber patch panels are designed for large-scale network environments such as data centers and server rooms. They fit seamlessly into standard 19-inch racks, providing high port density and centralized structured cabling management. AFL's portfolio includes modular and scalable solutions like the Denali High-Density Platform, LS Series, UltraSlim, U Series, and. A fiber patch panel is a mounted enclosure—either rack-mounted or wall-mounted—used to terminate, manage, and interconnect multiple fiber optic cables.

Read More
Large-capacity video memory AI server

Large-capacity video memory AI server

We strongly recommend a server grade platform like Intel Xeon® or AMD EPYC™ for hosting LLMs and applications using them. Those platforms have key features like lots of PCI-Express lanes for GPUs and storage, high memory bandwidth/capacity, and ECC memory support. Running large language models (LLMs), high-resolution Stable Diffusion or FLUX generations, or complex voice and video AI workflows efficiently requires a significant amount of GPU Video RAM (VRAM). This is one of the most important hardware specifications when choosing a graphics card for any kind. A server for local AI inference should not be chosen by the most expensive graphics card, but by whether the model, working cache and parallel requests fit into video memory, and whether the system has enough CPU resources, PCIe lanes, power and cooling. By the end of this article, readers will be equipped with the knowledge to make informed decisions about their AI.

Read More

Get In Touch

Connect With Us

📱

Spain (Sales & Engineering HQ)

+34 910 257 483

📍

Headquarters & Manufacturing

Calle de la Innovación 22, 28043 Madrid, Spain